October 2026
Expense parser: fine-tuning a small LLM on a Mac mini
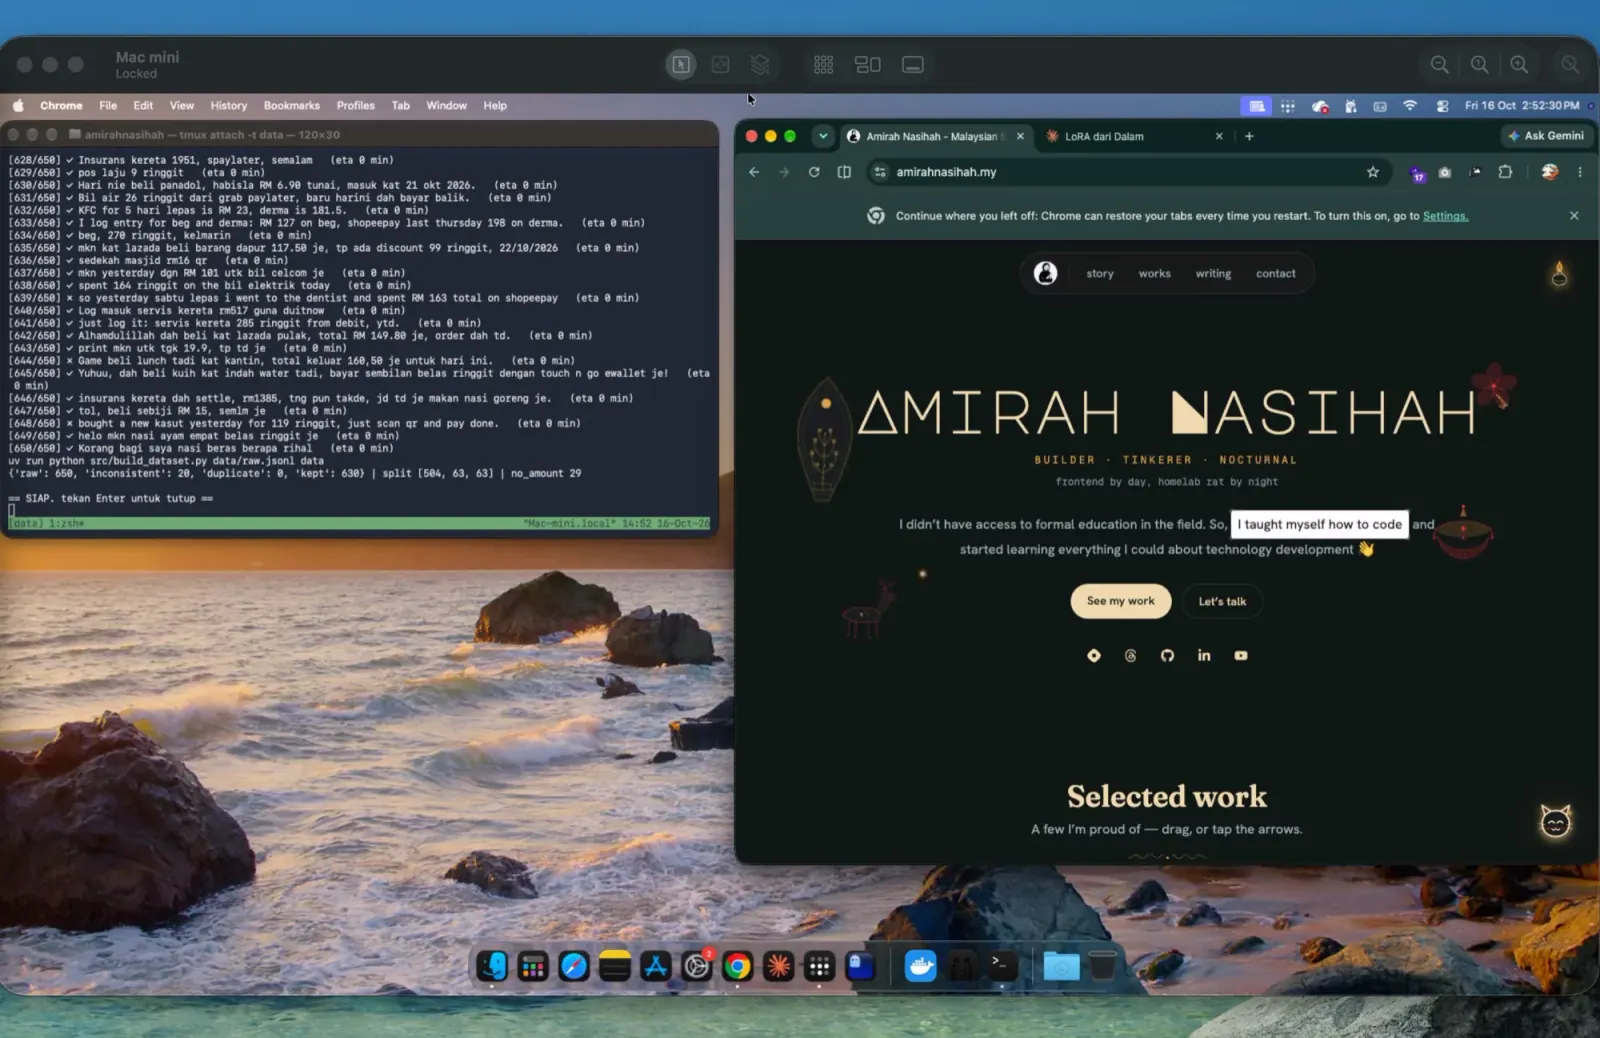
A learning experiment in supervised fine-tuning. "smlm mkn nasi lemak 8.50 tng" should come out as amount 8.50, food, e-wallet, yesterday, ready for my personal expense tracker. The question it answers with numbers: does a LoRA-tuned 1–2B model beat the same model with prompting alone, and Apple's on-device model? Everything runs on a Mac mini, so money messages never go to a cloud API. As of 18 Oct 2026 the dataset is built and training has not run yet; results will be added either way.
Teaching a small language model to turn casual Malay and English expense messages into structured records, with LoRA on Apple Silicon. In progress: dataset built, training next.
Teaching a small language model to turn casual Malay and English expense messages into structured records, with LoRA on Apple Silicon. In progress: dataset built, training next.
A learning experiment in supervised fine-tuning. "smlm mkn nasi lemak 8.50 tng" should come out as amount 8.50, food, e-wallet, yesterday, ready for my personal expense tracker. The question it answers with numbers: does a LoRA-tuned 1–2B model beat the same model with prompting alone, and Apple's on-device model? Everything runs on a Mac mini, so money messages never go to a cloud API. As of 18 Oct 2026 the dataset is built and training has not run yet; results will be added either way.
- Built a synthetic dataset pipeline: 650 ground-truth records, rewritten as casual BM, English and Manglish messages by a local 9B model, then a consistency filter that rejects any message disagreeing with its label (conflicting dates, stray numbers, missing amounts). 630 kept, split 504 / 63 / 63
- Comparison set up for four candidates (Qwen3 1.7B, Qwen3.5 2B, Gemma 4 E2B, FunctionGemma 270M) with identical LoRA settings on MLX, plus an ablation training only the last 8 of 28 blocks
- Each candidate is to be measured against its own prompted baseline (same system prompt plus 3 few-shot examples, no adapter) and Apple's on-device Foundation Model
- Success bar: at least 90% full-record accuracy (every field right) on 30 hand-typed messages the model never sees in training
- Status, 18 Oct 2026: dataset built; training and evaluation not yet run
More projects
view all →
First Hetzner VPS
First time renting and operating a real VPS, then growing it into a small personal lab: Hetzner as the always-on box, an old laptop on Debian as homelab, Tailscale + Termius for remote access, Ollama & Goose for local LLMs, reverse SSH / autossh / code-server to reach a MacBook through the VPS, Caddy (not nginx), Claude Code on the server, and openclaw powering PoketBot on Telegram — plus monitoring and subdomains on amrhnshh.com. Still learning CLI and server-side ops while vibe-coding.
Bui Notch
A black panel that merges with the MacBook notch. Collapsed it shows glanceable Claude session usage, to-dos due today, commits today, live agents, and time until the session limit resets. Hover unfurls a panel; click pins it open. Draws over the menu bar, follows Spaces, and click-throughs everywhere except the sliver. Open source under amirahnasihah/bui-notch.

XiaoZhi AI
A self-hosted backend for XiaoZhi ESP32 voice companions: wake word on device, then ASR → LLM → TTS and MCP tools through a server I control. Fork of xiaozhi-esp32-server, paired with the open-source xiaozhi-esp32 firmware (hands-on build logged separately as sihah-esp32).